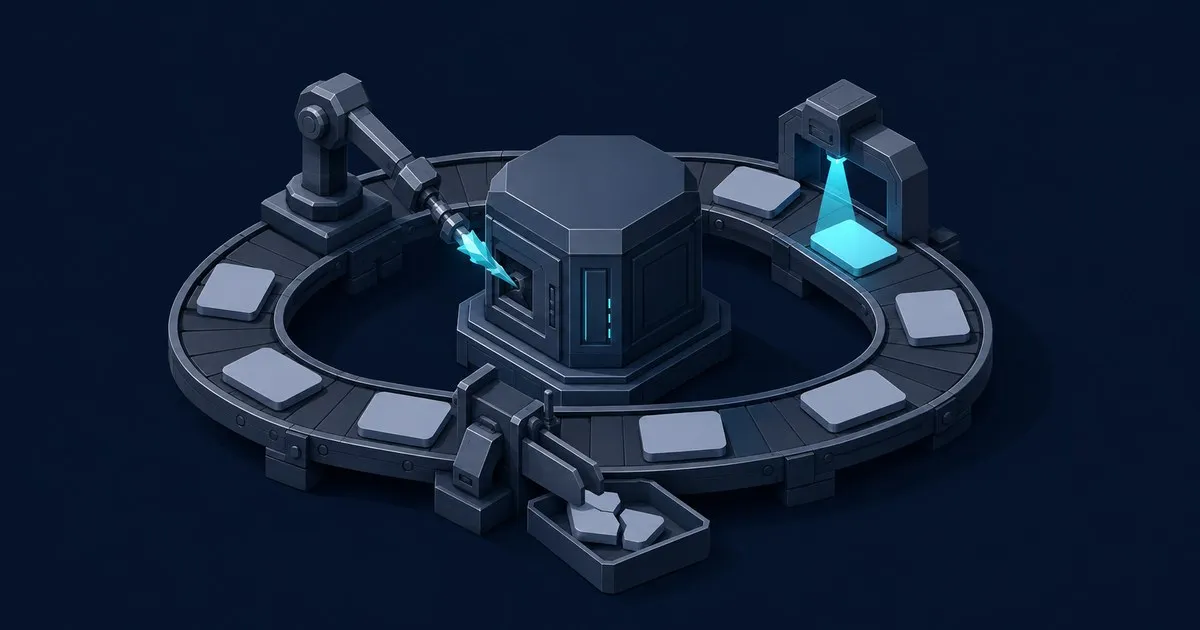
Understanding how LLM vulnerability scanners work is the difference between reading a scan report and trusting one. A scanner is not a CVE lookup against a version banner. It is an attack generator wired to a grader: it sends adversarial prompts to a target, collects the responses, and asks a second piece of software whether each response counts as a failure. Both halves are fallible, and the grader is where most of the uncertainty lives. garak, Microsoft’s PyRIT and promptfoo differ in packaging and vocabulary, but they run the same loop.
The scan loop, stage by stage
Target adapter. The scanner needs a uniform way to send a string and get a string back. garak calls this a generator and ships adapters for hosted APIs, Hugging Face models, local runtimes and a configurable REST endpoint. PyRIT calls the same abstraction a target, and per its documentation covers OpenAI, Azure, Anthropic, Google, Hugging Face, custom endpoints and web applications. This layer is why the same probe corpus can be pointed at a raw model one week and at the full application stack the next, and why those two runs produce different findings: the application has a system prompt, retrieval context and tools that the bare model does not.
Attack corpus. Each vulnerability class gets its own module carrying a pile of prompts. garak’s probes cover jailbreaks, prompt injection, toxicity, hallucination, data leakage, encoding attacks, malware generation and glitch tokens, among others. Promptfoo decomposes failure modes into plugins including harmful content and authorization bypass classes such as BOLA and BFLA. PyRIT ships datasets of standardized scenarios spanning content harms, psychosocial risks and data leakage. The corpus is the scanner’s coverage ceiling: nothing outside it gets tested.
Mutation. Static prompt lists get patched quickly, so scanners transform payloads before delivery. PyRIT calls these converters, garak calls them buffs. Base64, ROT13, translation, character substitution and similar wrappers turn one blocked payload into dozens of candidate bypasses.
Delivery and orchestration. Single-turn delivery sends one prompt and reads one response. Multi-turn orchestration is where modern scanners earn their keep, because the interesting jailbreaks are conversational. Microsoft’s documentation lists Crescendo, TAP and Skeleton Key among PyRIT’s built-in attack strategies, with a memory layer persisting conversations and scores to SQLite or Azure SQL so a run is reproducible and reviewable afterward.
Detection. garak pairs each probe with detectors that decide whether the output exhibits the targeted failure. Promptfoo’s docs describe grading with “deterministic and model-graded metrics.” PyRIT’s scorers return true/false, Likert-scale or classifier verdicts, including Azure AI Content Safety and LLM-based scoring.
Scoring and reporting. garak writes a fresh JSONL report per run recording both generation attempts and evaluation results, plus a dedicated hit log for attempts that revealed a weakness, and prints per-probe failure rates to the console. That structured output is what makes a CI gate possible: you threshold on a rate, not on a human reading prose.
The detector, not the payload, decides report quality
Payload libraries are cheap to copy. Deciding whether a given response is a compliance is the expensive part, and every technique in use has a failure mode. Keyword and regex detectors are fast and deterministic but miss paraphrase and fire on any output that merely discusses the forbidden topic. Trained classifiers generalize better and carry their own distribution gaps. LLM-as-judge grading is the most flexible option and the least stable one: the MT-Bench and Chatbot Arena paper reports that strong judges reach “over 80% agreement” with human preference, the same level humans reach with each other, while documenting position, verbosity and self-enhancement biases plus limited reasoning ability. That work grades preference rather than safety, but the biases transfer, and a self-enhancement bias matters a lot when the judge model and the target model come from the same family.
Practical consequence: treat a scanner’s raw hit count as a triage queue, not a finding list. Sample the hits, read the transcripts, and calibrate the detector against your own application before you let a number gate a deploy.
One refusal is not a pass
LLM output is stochastic, so a single-shot test measures almost nothing. Scanners handle this by repetition: garak’s README states the tool produces multiple outputs per prompt by default, ten generations each. The unit of measurement becomes an attack success rate over N attempts rather than a boolean. A model that refuses a jailbreak nine times and complies once has a 10% success rate on that probe, and in an agentic deployment that single compliance is the incident.
This is also why scan results do not transfer across model versions, temperature settings or system-prompt edits. The garak framework paper puts it plainly: “LLM security is a moving target,” and “what constitutes a security weak in one context may not be an issue in a different context.”
The other scanner family: artifacts, not behavior
Behavioral scanners test what a model does. Artifact scanners test what a model file contains, and they work nothing alike. ModelScan targets model serialization attacks, where malicious code is embedded during save and executes on load. Per the project docs it reads the file byte by byte without executing it, looking for unsafe code signatures across pickle, TensorFlow protobuf, H5 and Keras V3 formats, ranks findings CRITICAL through LOW, and returns exit code 0 for clean, 1 for findings and 2 for error.
That is a deterministic, build-time control with an unambiguous verdict, which makes it the easier of the two to gate on. Run it before you load any third-party checkpoint, not after.
Where each scan belongs in the pipeline
Three enforcement points, three different tools. Artifact scanning goes at build time, on every pulled or produced checkpoint. Behavioral scanning goes pre-deploy and on every prompt, model or retrieval change, since all three alter the attack surface. Neither one protects a request in flight: that is the job of a runtime guardrail or content-safety classifier, which is a separate control with its own false-positive and latency budget. Scanners tell you what to fix; guardrails hold the line while you fix it.
For mapping findings to a shared vocabulary, MITRE ATLAS catalogs adversary techniques against AI systems, and the OWASP LLM Top 10 gives you risk IDs your AppSec team already tracks. Attack technique background, including how the conversational jailbreaks these tools automate actually work, is covered in depth at aisec.blog.
What a clean scan does not prove
A green run means the payloads in that corpus, graded by that detector, did not trip that build. It does not mean the class is closed. OWASP is explicit on the hardest case: “Given the stochastic influence at the heart of the way models work, it is unclear if there are fool-proof methods of prevention for prompt injection” (LLM01:2025). Scanners are a measurement instrument inside a layered control set, which is how NIST AI 600-1 frames it: action MS-2.7-007 calls for AI red-teaming against prompt injection alongside adversarial examples, data poisoning, membership inference and model extraction, as a recurring measurement activity rather than a one-time certificate.
Three residual gaps survive any scan. Coverage is corpus-bound, so novel techniques are invisible until someone writes a probe. Detector error is bidirectional, so both your hit count and your clean count are estimates. And most published corpora target the model, not your orchestration: tool allowlists, RAG context isolation and agent sandboxing need application-specific tests you write yourself. Tool-by-tool differences in how these stages are implemented are covered in the garak guide, the PyRIT walkthrough and the CI integration comparison.
Related across the network
- 40 AI Security Tools Compared: 2026 Directory — aisecbench.com
- AI Security Tools by Defense Category — bestaisecuritytools.com
- A Practical Guide to AI Red-Teaming for Security Teams — ai-alert.org


